Distinguishing itself through its advanced reasoning capabilities, native multimodality, and expansive context window. This article delves into what makes Gemini 2.5 Pro unique and how it stacks up against other leading LLMs.
What Makes Gemini 2.5 Pro Unique?
- Native Multimodality: Unlike many LLMs, Gemini 2.5 Pro has the following architecture:
- Unified Architecture: Gemini was designed and trained from its inception to understand and process different modalities (text, images, audio, video) together, within a single model architecture. This means that when Gemini “sees” an image and reads text about it, or hears an audio description of a video, it processes all of that information through the same neural network. There isn’t a separate vision model, then an audio model, then a language model, with their outputs “stitched together” at a later stage.
- Intermodal Reasoning: Because it’s trained end-to-end on multimodal data, Gemini can develop a deeper, more inherent understanding of how different modalities relate to each other. It can reason about the connections between visual information, spoken words, and written text seamlessly. This leads to more nuanced comprehension and the ability to generate responses that truly integrate insights from all input types. For example, it can understand a joke where the visual component is crucial to the punchline, or debug code by analyzing a screenshot of an error message alongside the code itself.
- Advanced “Thinking” and Reasoning: Gemini 2.5 Pro is designed to “reason” internally before generating a response. This means it can methodically break down complex tasks, explore multiple hypotheses, and build a response step-by-step, rather than jumping straight to an answer. This “Deep Think mode” enhances accuracy and makes it particularly strong in areas requiring complex problem-solving, such as coding, mathematics, and scientific analysis. It can even independently write, modify, debug, and refine code with minimal human supervision.
- Expansive Context Window: With a context window of up to 1 million tokens (and even higher for some use cases), Gemini 2.5 Pro can process vast amounts of data in a single query. This enables it to analyze lengthy documents, handle extensive codebases, and synthesize information from multiple sources, making it highly effective for tasks like long-context reading comprehension and deep data analysis.
- Agentic Capabilities: Gemini 2.5 Pro exhibits strong agentic capabilities, meaning it can interact with external tools and services. This allows it to execute code, perform searches, structure data in specific formats (like JSON), and even make calls to local businesses to get information, streamlining complex workflows.
- Enhanced Coding Performance: Google has specifically focused on improving Gemini 2.5 Pro’s coding abilities. It excels at front-end and UI development, transforming and editing code, and creating sophisticated agentic workflows, often outperforming other models in benchmarks like WebDev Arena.
How it is better than other LLMs:
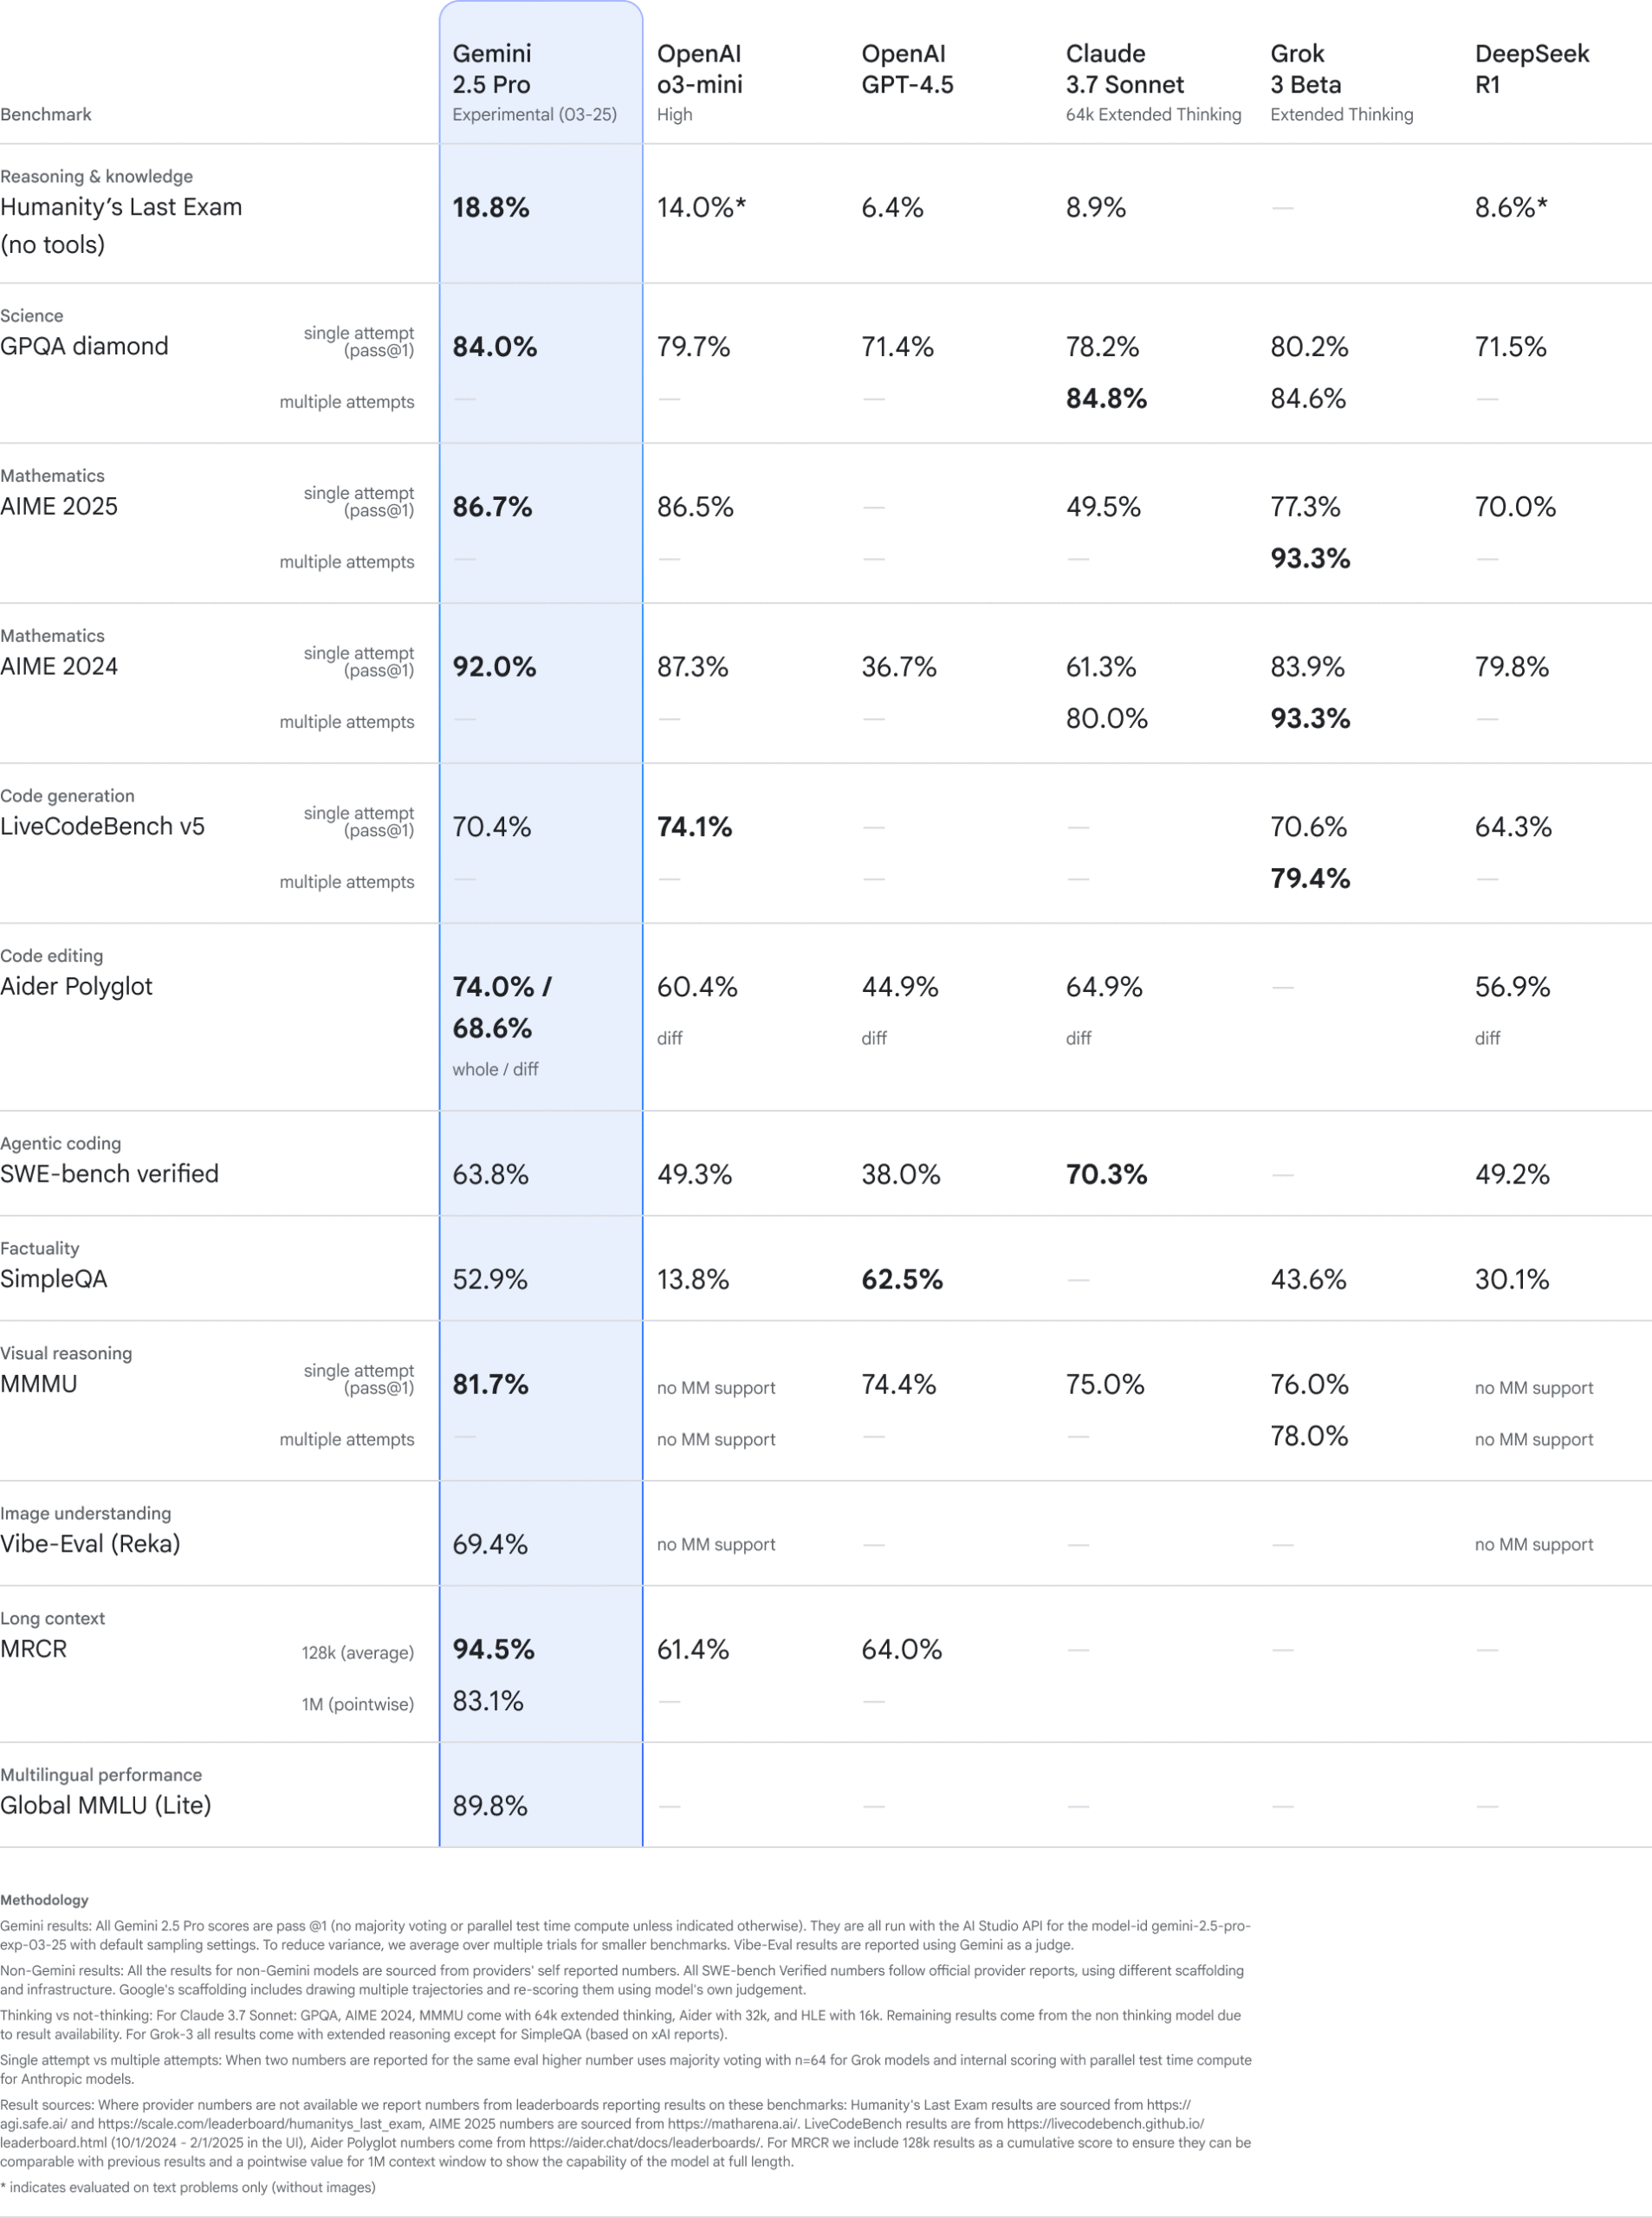
Enhanced Reasoning:
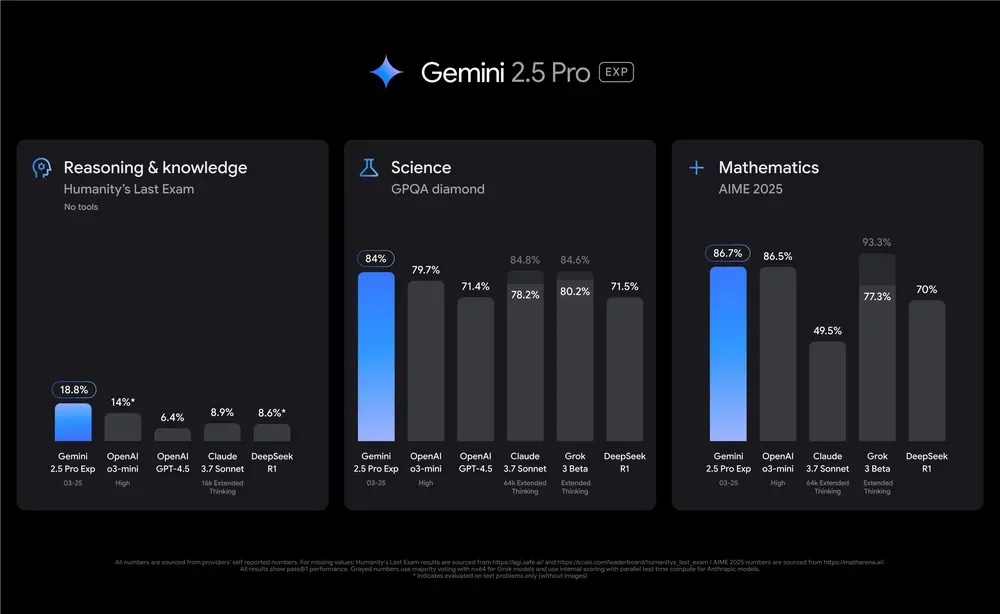
It’s important to note that the AI landscape is rapidly evolving, and performance comparisons can be nuanced and subject to specific benchmarks and use cases. However, Gemini 2.5 Pro’s core strengths in reasoning, multimodality, and long-context understanding position it as a leading contender in the LLM space.